Jev: intelligence for an ordinary if statement (#AI4SDLC)
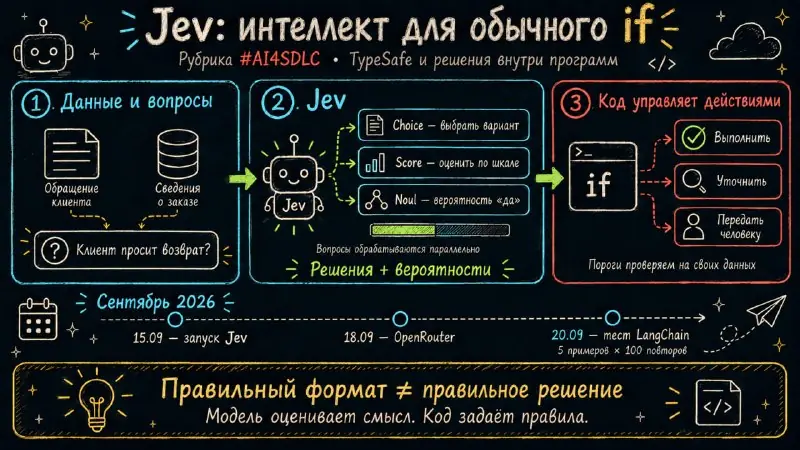
In the previous post, Diogo Almeida proposed training AI to make decisions that fit inside ordinary software. That idea now has a tangible follow-up: Jev, a model from his company TypeSafe. What is interesting here is how many capabilities the developers were willing to give up for one useful property: answering small questions quickly.
On September 15, 2026, TypeSafe opened early access to Jev and announced a $40 million funding round led by DCVC. The model does not generate free-form text at all. It receives a state, such as a customer’s message and order details, plus a set of questions with predefined answer formats:
- Choice selects an option from a list: which queue should handle the request;
- Score evaluates against a defined scale: how urgently help is needed;
- Noul returns the probability of a “yes” answer: whether the customer is asking for a refund.
The questions are evaluated in parallel; Choice and Score also return probabilities for the possible answers. Ordinary code then decides what to do: route the ticket to the right team, request missing information, or hand it to a person. The model can sit inside a familiar if statement while the program keeps the rules for moving between steps. These are the pieces automation is built from.
TypeSafe calls its training method RLCD — Reinforcement Learning for Calibrated Decisions. Its stated goal is to align probabilities with observed event frequencies. If the model repeatedly says “80% probability,” the event should occur in roughly 80% of those cases. That would let developers choose a threshold for automatic action and send uncertain cases for review. Of course, that calibration still needs to be tested on your own data.
Giving up generation is supposed to deliver a substantial speed dividend. In its own workflow evaluations, TypeSafe reported speedups of up to 193.6 times and costs up to 444.6 times lower than the LLMs it compared against. The company itself treats these figures as an optimistic guide to potential real-world gains. There is also a methodological wrinkle: the reference was an average of strong models’ answers, so the test measured agreement with those models rather than independently established correctness.
External experiments have started to appear too. On September 20, LangChain published a test in which Jev judged five responses from a weather agent, 100 times each. All 500 binary judgments matched a human reviewer’s labels, and the average call took 0.44 seconds. Encouraging, but five distinct examples are still five: repetitions are useful for measuring consistency, while breadth of capability needs separate testing.
The slipperiest phrase in the announcement is “can’t hallucinate.” What is guaranteed here is the answer’s form: Jev cannot invent a sixth category when the developer has allowed five. It can certainly choose the wrong one of those five. The documentation is quite direct about its difficulties: arithmetic, date comparisons, long reasoning chains, and irrelevant context. Malicious instructions contained in the data can also influence its decisions.
An interesting experiment with Jev, then, is to isolate a small part of an existing process that repeatedly needs a judgment about meaning. For example, checking whether a source supports an agent’s conclusion or choosing a route for handling a ticket. Measure errors, choose a threshold, and keep a way to hand the task to a person. If that component works cheaply and predictably, it can run at every step, becoming a building block for a more complex system.
You can try it through OpenRouter: model typesafe/jev-1.13, priced on September 20 at $0.042 per million input tokens, with free output. A good reason to take one recurring branch in your code and measure the change in latency and errors.
#AI4SDLC #AI #Architecture #Evals #Engineering